
16:01Machine-translated from Azerbaijani by AIRead in Azerbaijani
Microsoft Unveils Fast AI Model for Real-Time Speech-to-Text Transcription
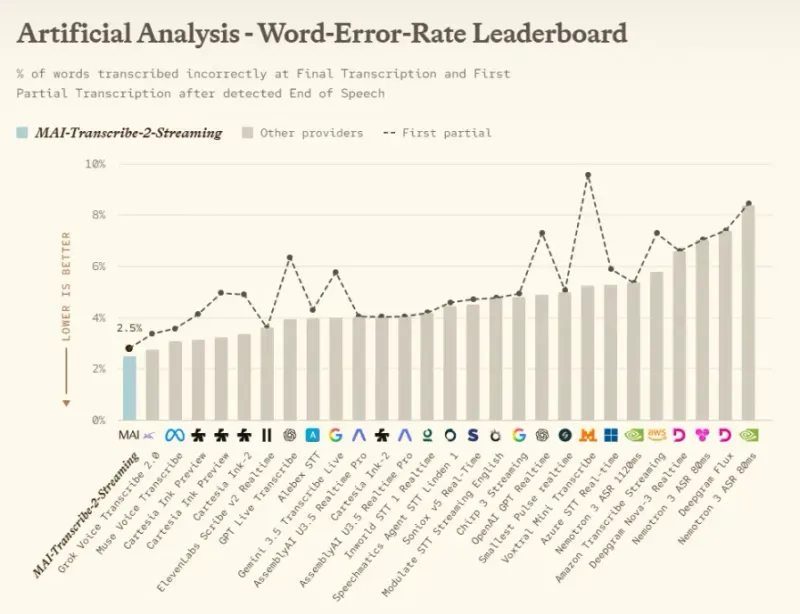
Microsoft has expanded its MAI artificial intelligence family by introducing three new audio models for speech processing. The highlight of the new releases is the MAI-Transcribe-2-Streaming model. It is Microsoft’s first streaming AI model designed to convert speech into text in real time.
While the standard MAI-Transcribe-2 model processes only prerecorded audio files, the Streaming version begins displaying the first parts of the text just 100 milliseconds after receiving an audio signal. As the conversation continues, the model takes new context into account and continually revises the words displayed on the screen, ultimately producing a more accurate transcript.
The model can automatically identify 60 languages during a conversation and switch seamlessly between them. According to Microsoft’s internal tests, words appear on the screen twice as quickly as with the company’s “closest competitor” during dictation and captioning. Microsoft did not name that competitor.
The company also introduced two new generative voice models that expand the capabilities of technologies previously used on the Azure Voice Live platform. The flagship MAI-Voice-2.1 model supports 23 languages across 26 locales. This technology allows a voice created in one language to switch to other languages while speaking, while preserving the speaker’s vocal identity and the natural accent appropriate to each language.
A lighter version called MAI-Voice-2.1-Flash was also introduced for systems handling heavier workloads. The model can synthesize 45 seconds of audio with approximately 150 milliseconds of latency. According to Microsoft, this version is 55% faster and 60% cheaper than comparable alternatives. The company did not name those alternatives.
Both voice models also support the secure cloning of copyrighted voices using a sample lasting a few seconds. This feature makes it possible to use a specific voice sample to generate speech resembling that voice.
According to Microsoft, all three new models are now available to developers through Microsoft Foundry, MAI Playground, Azure Voice Live, and Vercel. Trial pricing for MAI-Transcribe-2-Streaming will remain in effect through the end of 2026, with one hour of audio streaming processing costing $0.54.
For voice synthesis, MAI-Voice-2.1 is priced at $22 per 1 million characters, while the Flash version costs $15.